

The client
The client is a large financial services enterprise headquartered in London, with offices and operational centers across Europe.
Its business depends on systems, offices and teams that keep running. When something goes wrong, business, technical and support teams all have a part in the response, and delays reach customers quickly.
The challenge
Incidents were reported, but the response ran on emails, calls, manual escalation and coordination between many people. Without structured tracking, resolution was slow and the same disruptions came back.
- Incidents were reported and escalated by email and phone.
- Ownership was unclear once several teams were involved.
- Critical incidents were not escalated consistently.
- Nobody had a clear view of incident status, priority or progress.
- Repeated disruptions were hard to spot and prevent.
What they set up in Asset Infinity
The enterprise centralized incident reporting and tracking in Asset Infinity’s Work feature, with priorities by operational impact, named owners and escalation for critical incidents.
One place to report
Staff in any office raise an incident from the web or mobile app, choosing its category, so every incident is recorded the same way. (Work)
Priority by impact
Incident priorities are defined by operational impact and response need, and each priority carries its own SLA response and resolution targets. (Work)
Owners and escalation
Each incident is assigned to the right technical or operational team. Critical incidents that wait too long escalate to a supervisor. (Work)
Incident status at a glance
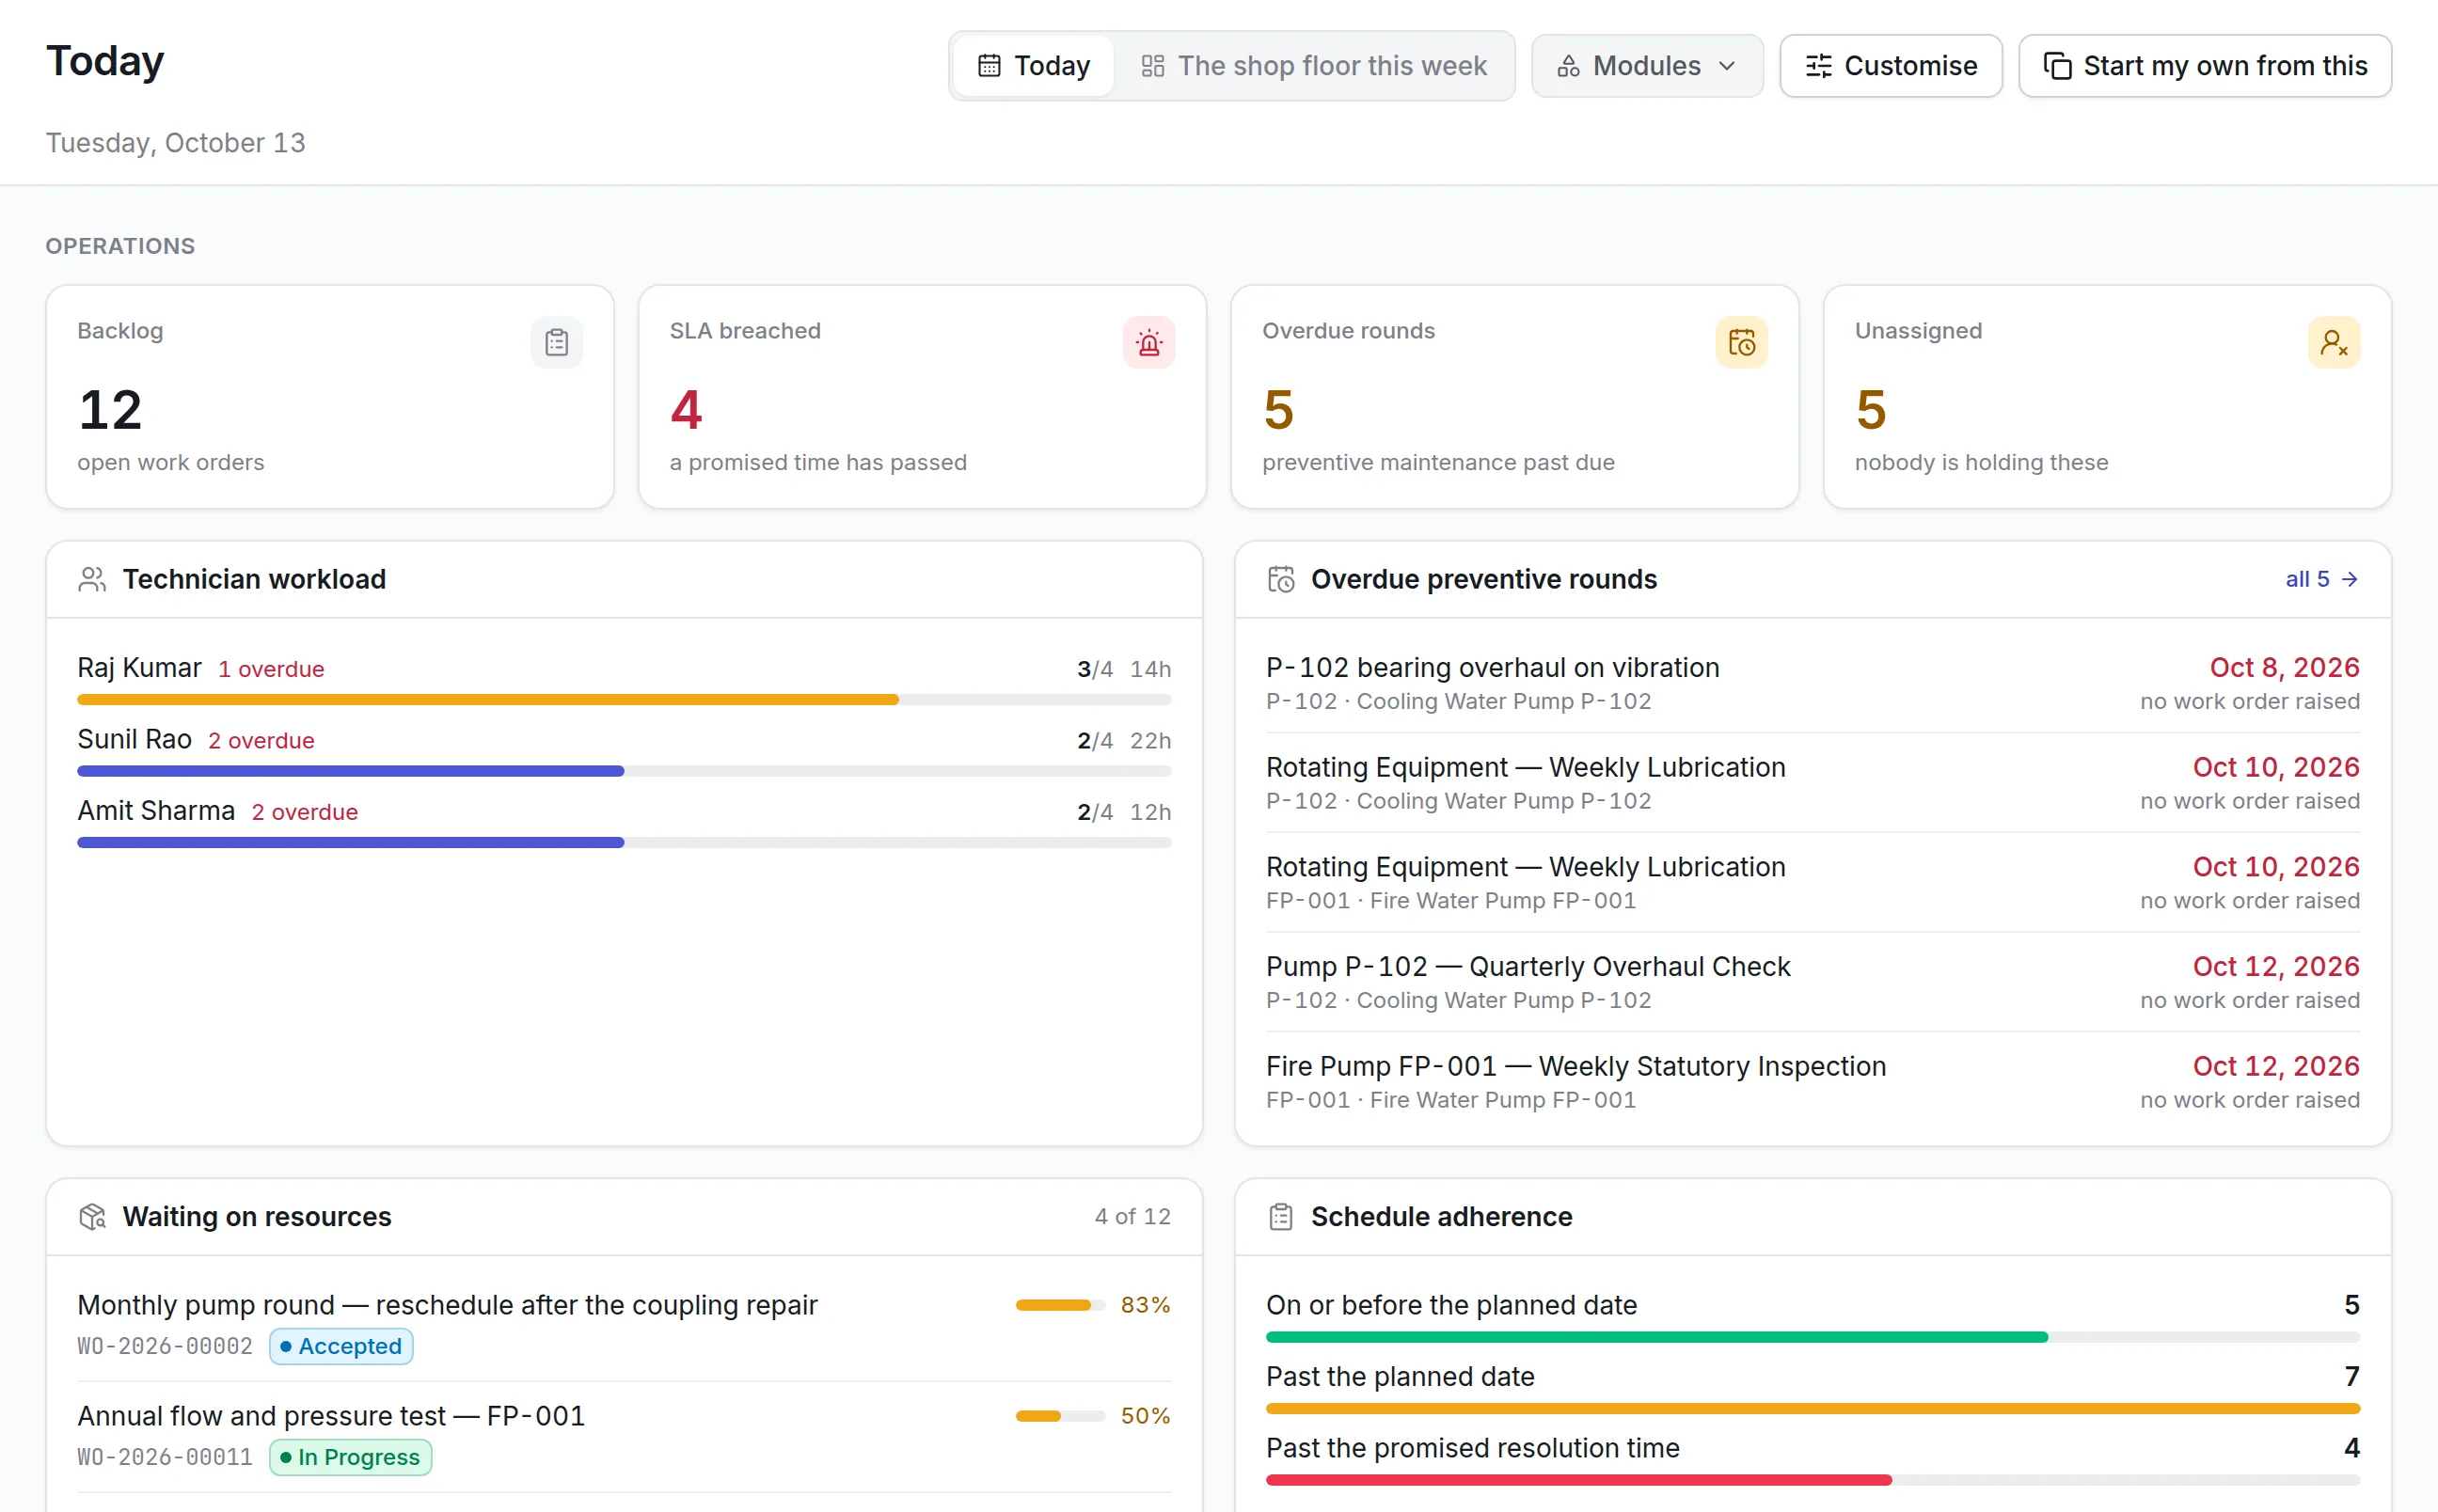
Dashboards show open incidents by priority, owner and status, and reports show which categories keep recurring. (Insight)
How it works day to day
Here is how an operational incident is handled now.
- Staff member: reports the incident. From the web or mobile app, the person who sees the problem raises an incident with its category and a description.
- Service desk: sets the priority. The service desk confirms the priority based on operational impact, which sets the response and resolution targets.
- System: routes it to the owning team. The incident goes to the technical or operational team responsible, and a named owner is notified.
- System: escalates when it waits. SLA timers run against the priority. A critical incident that is not picked up or resolved in time escalates to a supervisor.
- Support engineer: investigates and updates. The owner records findings and actions on the incident and messages other teams there, so everyone sees the same history.
- Support engineer: resolves and closes. Once service is restored, the incident is closed with what was done, and the person who reported it sees the outcome.
- Operations manager: reviews recurring incidents. Reports show incidents by category, priority and time to resolve, pointing to disruptions that keep coming back.
Before and after
| Before | With Asset Infinity | |
|---|---|---|
| Reporting | Emails and calls | One incident record from web or mobile |
| Priority | Decided case by case | Set by operational impact |
| Ownership | Unclear across teams | A named owner on every incident |
| Escalation | Manual, inconsistent | Automatic for incidents that wait too long |
| Visibility | Limited | Status, priority and progress on dashboards |
| Repeat disruptions | Hard to spot | Recurring categories visible in reports |
How it rolled out
- Response practices reviewed. The team reviewed incident categories, response practices, escalation gaps and past disruptions.
- Priorities, owners and escalation set up. Priorities, team assignment and escalation paths were configured for business, technical and support teams.
- Teams trained and refined. Teams were trained on reporting, tracking, escalating and resolving incidents. The setup was refined as it was used.
The results
- Faster identification, assignment and response to operational incidents
- Support teams coordinated through clear incident ownership
- Clearer visibility into incident status, priority and progress
- Less disruption to critical business operations
- Stronger response discipline across business, technical and support teams
Why it worked
Priority by impact
Defining priorities by operational impact meant the most disruptive incidents got the fastest response.
Escalation that does not wait
Critical incidents escalate on a timer, so they no longer depend on someone remembering to chase them.
One history per incident
Findings, actions and messages stay on the incident, so teams coordinate in one place and later reviews have the full story.
Looking ahead
The enterprise moved from fragmented incident handling to one way of reporting, assigning, prioritizing, escalating and resolving incidents across its offices.
With every incident recorded by category and impact, teams can see which disruptions recur and act on the cause, which supports business continuity over time.